

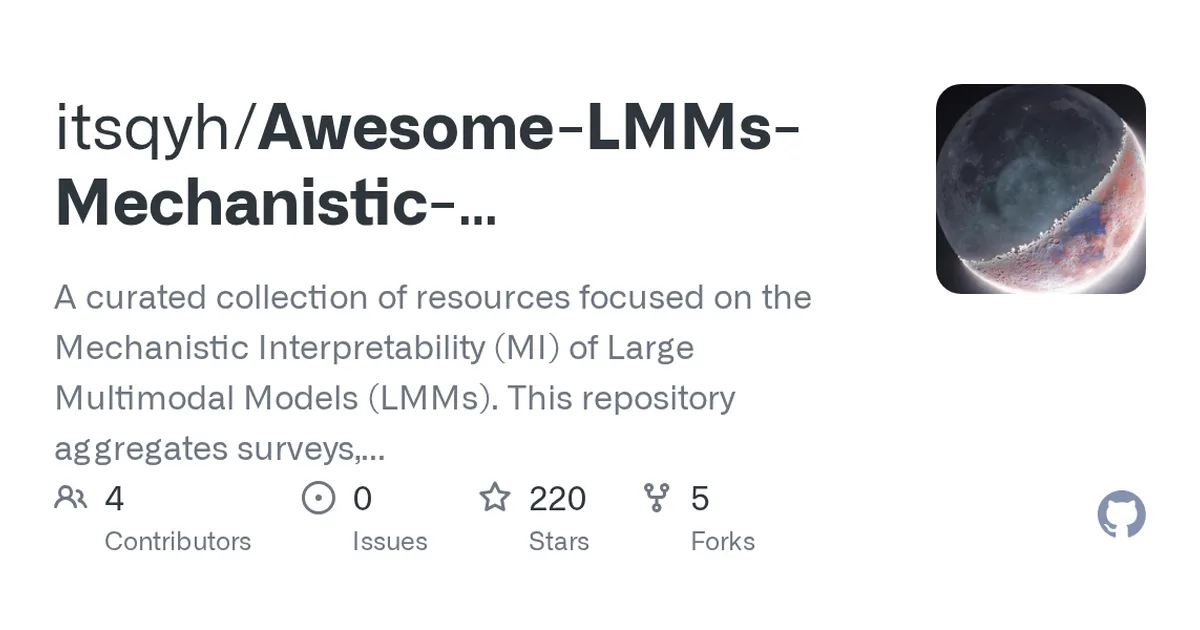
Awesome-LMMs-Mechanistic-Interpretability
一站式读懂多模态模型内部工作原理
项目预览
项目数据
项目介绍
Star 增长趋势
本站每日记录该项目 GitHub 星标变化,观测越久曲线越完整
数据来源:GitHub API 逐日快照 · 收录于 2026-08-09 · 当前星标 ★ 223
技术标签
核心亮点
- 聚焦细分领域,资源分类清晰,便于快速定位相关论文
- 收录了综述、博客和研究论文,兼顾入门与深度研究
- 紧跟前沿,持续更新,适合跟踪该方向最新进展
不足之处
- 项目处于早期,资源数量有限,覆盖尚不全面
- 文档/社区待观察
适用场景
- 研究多模态模型可解释性的学者快速检索文献
- 入门者了解LMMs内部机制的学习路径
- 为模型安全性和对齐研究提供参考资源
替代项目
Awesome-Mechanistic-Interpretability、Awesome-LLM-Interpretability、LMMs-Eval
下一篇:search-arena
同类项目推荐
 SREGym
开源
用真实生产事故考题,测出 AI Agent 会不会排障
Can AI agents resolve production incidents?
 langtest
开源
给大模型做全面体检,上线前揪出安全漏洞
Deliver safe & effective language models
 appworld
开源
在真实模拟世界里,测试你的 AI 智能体会不会办事。
AppWorld: A Controllable World of Apps and People for Benchmarking Function Calling ···
 awesome-llm-security
开源
一站式找到 LLM 安全工具和资料,防坑避雷
A curation of awesome tools, documents and projects about LLM Security.
 hol-guard
开源
给 AI 代理装杀毒软件,实时拦截危险操作和攻击
Open-source antivirus and firewall for AI agents: block risky tools, secret access, ···
 WorldLens
开源
给自动驾驶世界模型做全科体检,从生成到重建一测到底
[CVPR 2026 Oral] WorldLens: Full-Spectrum Evaluations of Driving World Models in Rea···
 terminal-bench
开源
在真实终端里跑任务,量出 agent 到底行不行
Measuring and evolving with the frontier of agent work
 awesome-agent-skills-security
开源
一份清单看懂 Agent 工具调用的攻击与防御
️ A curated list of resources on agent skills security: attacks, defenses, framewor···
 TrustLLM
开源
给大模型做全面体检,量化可信度短板
[ICML 2024] TrustLLM: LLM trustworthiness evaluation across truthfulness, safety, fa···