

项目预览
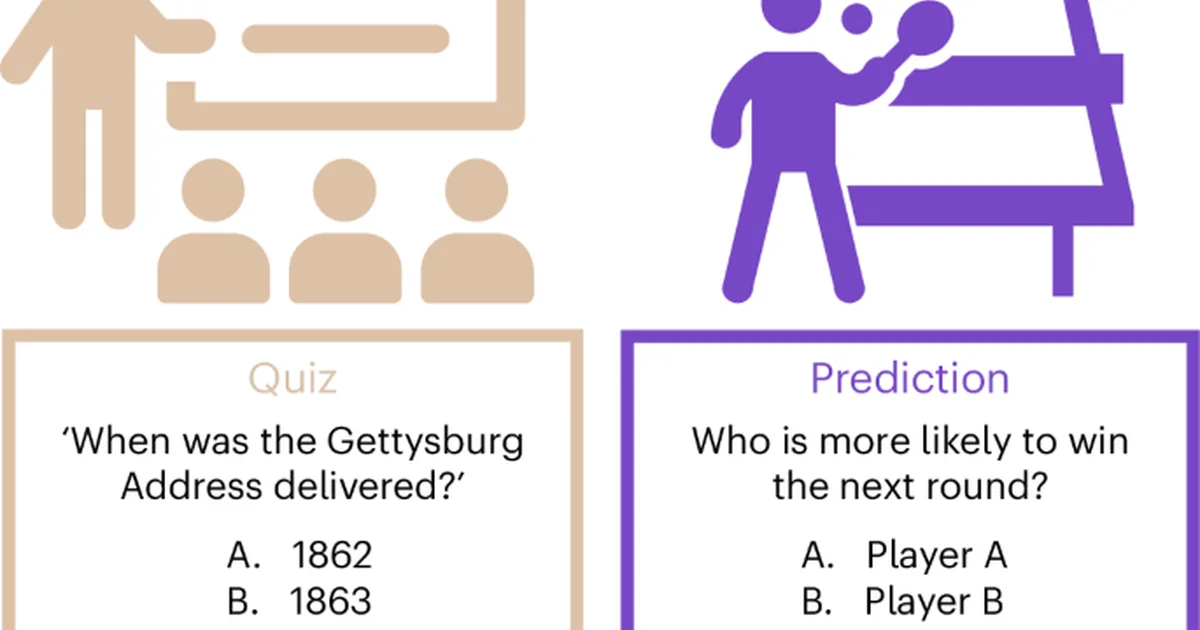
项目数据
项目介绍
Star 增长趋势
本站每日记录该项目 GitHub 星标变化,观测越久曲线越完整
数据来源:GitHub API 逐日快照 · 收录于 2026-08-09 · 当前星标 ★ 85
核心亮点
- 提供标准化评测基准,可复现论文中的对比结果
- 支持多种LLM接入,方便横向比较模型科学推理能力
- 数据集基于真实论文,具有实际科学价值
不足之处
- 文档较少,使用门槛较高
- 评测领域仅限神经科学,通用性有限
适用场景
- 评估LLM在科学领域的知识深度
- 对比AI与人类专家的预测能力
- 作为科学发现AI的基准测试
替代项目
SciBench、MMLU、BIG-bench
上一篇:ICSFSurvey
下一篇:CS-Eval
同类项目推荐
 xFinder
开源
用AI自动评估AI,让模型评测更可靠、更省力
[ICLR 2025] xFinder: Large Language Models as Automated Evaluators for Reliable Eval···
 deepteam
开源
自动模拟越狱攻击,提前测出 LLM 安全漏洞
DeepTeam is a framework to red team LLMs and AI agents.
 Frontier-CS
开源
用开放式 CS 难题测出大模型的真实上限
A benchmark for evaluating LLMs on open-ended CS problems. Exploring the Next Fronti···
 LLM-IR-Bias-Fairness-Survey
开源
一库看懂LLM做搜索时的偏见与公平坑
This is the repo for the survey of Bias and Fairness in IR with LLMs.
 safe-clip
开源
给 CLIP 模型装上安全阀,自动过滤 NSFW 内容
[ECCV 2024] Official implementation of Safe-CLIP, a safety-aligned vision-language m···
 GLM-5.3-Flash-J-Space-Capability···
开源
把大模型智能体能力评测做成可读报告,一眼看清真实水平
GLM-5.3-Flash × J-Space capability realization — benchmark presentation of the J-S···
 ATM-Bench
开源
测测AI能否记住你4年前的琐事
ATM-Bench: A benchmark for long-term personalized memory QA spanning ~4 years of mul···
 confabulations
开源
测出RAG系统胡说八道,用人工验证问答对量化幻觉
Hallucinations (Confabulations) Document-Based Benchmark for RAG. Includes human-ver···
 Doberman-Core
开源
运行时拦截 AI 的每个动作,防止危险操作执行
Your AI's guard dog. Doberman sits at runtime, gating every input, output and tool c···